[{"@type":"PropertyValue","name":"Content","value":"Contest questions text;"},{"@type":"PropertyValue","name":"Data Size","value":"About 114,000;"},{"@type":"PropertyValue","name":"Data Fields","value":"Contains title, answer, parse, subject, grade, question type, knowledge, has_img, There are some questions without parse;;"},{"@type":"PropertyValue","name":"Subject categories","value":"Primary, middle and high school science questions;"},{"@type":"PropertyValue","name":"Format","value":"Jsonl;"},{"@type":"PropertyValue","name":"Language","value":"Chinese;"},{"@type":"PropertyValue","name":"Data processing","value":"Subject, questions, parse and answers were analyzed, formula conversion and table format conversion were done, and content was also cleaned"}]
{"id":1733,"datatype":"1","titleimg":"https://www.nexdata.ai/shujutang/static/image/index/datatang_tuxiang_default.webp","type1":"226","type1str":null,"type2":"227","type2str":null,"dataname":"114K Chinese Olympiad Questions Dataset – STEM & QA","datazy":[{"title":"Content","content":"Contest questions text;","desc":"Content"},{"title":"Data Size","content":"About 114,000;","desc":"Data Size"},{"title":"Data Fields","content":"Contains title, answer, parse, subject, grade, question type, knowledge, has_img, There are some questions without parse;;","desc":"Data Fields"},{"title":"Subject categories","content":"Primary, middle and high school science questions;","desc":"Subject categories"},{"title":"Format","content":"Jsonl;","desc":"Format"},{"title":"Language","content":"Chinese;","desc":"Language"},{"title":"Data processing","content":"Subject, questions, parse and answers were analyzed, formula conversion and table format conversion were done, and content was also cleaned","desc":"Data processing"}],"datatag":"Contest Questions,LLM,Text","technologydoc":null,"downurl":null,"datainfo":null,"standard":null,"dataylurl":null,"flag":null,"publishtime":null,"createby":null,"createtime":null,"ext1":null,"samplestoreloc":null,"hosturl":null,"datasize":null,"industryPlan":null,"keyInformation":"","samplePresentation":[{"name":"1.png","url":"https://storage-product.datatang.com/damp/product/sample_presentation/20250715145112/1.png?Expires=4102415999&OSSAccessKeyId=LTAI5tEBeSWUJiqjXvBMsxEu&Signature=AcAwLSjMBTpjcuucVZx7%2FNfbngE%3D","intro":"","size":161726,"progress":100,"type":"jpg"},{"name":"2.png","url":"https://storage-product.datatang.com/damp/product/sample_presentation/20250715145112/2.png?Expires=4102415999&OSSAccessKeyId=LTAI5tEBeSWUJiqjXvBMsxEu&Signature=RfRkQc1UU%2BvxnyGOUKoCfInKRcU%3D","intro":"","size":313903,"progress":100,"type":"jpg"},{"name":"3.png","url":"https://storage-product.datatang.com/damp/product/sample_presentation/20250715145112/3.png?Expires=4102415999&OSSAccessKeyId=LTAI5tEBeSWUJiqjXvBMsxEu&Signature=ZpdioBOYCwvS2yN1hZOvjNS26Lw%3D","intro":"","size":112666,"progress":100,"type":"jpg"}],"officialSummary":"This dataset includes 114,000 structured Chinese academic contest questions from primary, middle, and high school levels. Subjects covered include mathematics, physics, chemistry, and biology. Each question is annotated with the question title, correct answer, parse (explanation), subject, grade level, and question type, making it highly suitable for fine-tuning educational large language models (LLMs) and intelligent tutoring systems. The data mirrors real-world Olympiad and competitive test formats in China, providing rich material for enhancing subject-specific knowledge and reasoning capabilities in AI systems. All data complies with global privacy regulations including GDPR, CCPA, and PIPL.","dataexampl":null,"datakeyword":["Chinese exam dataset","Chinese contest questions","Olympiad question dataset","parsed Chinese QA","AI dataset for Chinese education","NLP training Chinese STEM","math Olympiad Chinese","education QA data"],"isDelete":null,"ids":null,"idsList":null,"datasetCode":null,"productStatus":null,"tagTypeEn":"Type","tagTypeZh":null,"website":null,"samplePresentationList":null,"datazyList":null,"keyInformationList":null,"dataexamplList":null,"bgimg":null,"datazyScriptList":null,"datakeywordListString":null,"sourceShowPage":"llm","dataShowType":"[{\"code\":\"0\",\"language\":\"ZH\"},{\"code\":\"1\",\"language\":\"ZH\"},{\"code\":\"2\",\"language\":\"EN,PT,DE,KO,FR,ES\"},{\"code\":\"3\",\"language\":\"EN\"},{\"code\":\"4\",\"language\":\"JP\"}]","productNameEn":"114,000 - Chinese Contest Questions Text Parsing And Processing Data","BGimg":"","voiceBg":["/shujutang/static/image/comm/audio_bg.webp","/shujutang/static/image/comm/audio_bg2.webp","/shujutang/static/image/comm/audio_bg3.webp","/shujutang/static/image/comm/audio_bg4.webp","/shujutang/static/image/comm/audio_bg5.webp"]}
114K Chinese Olympiad Questions Dataset – STEM & QA
Chinese exam dataset
Chinese contest questions
Olympiad question dataset
parsed Chinese QA
AI dataset for Chinese education
NLP training Chinese STEM
math Olympiad Chinese
education QA data
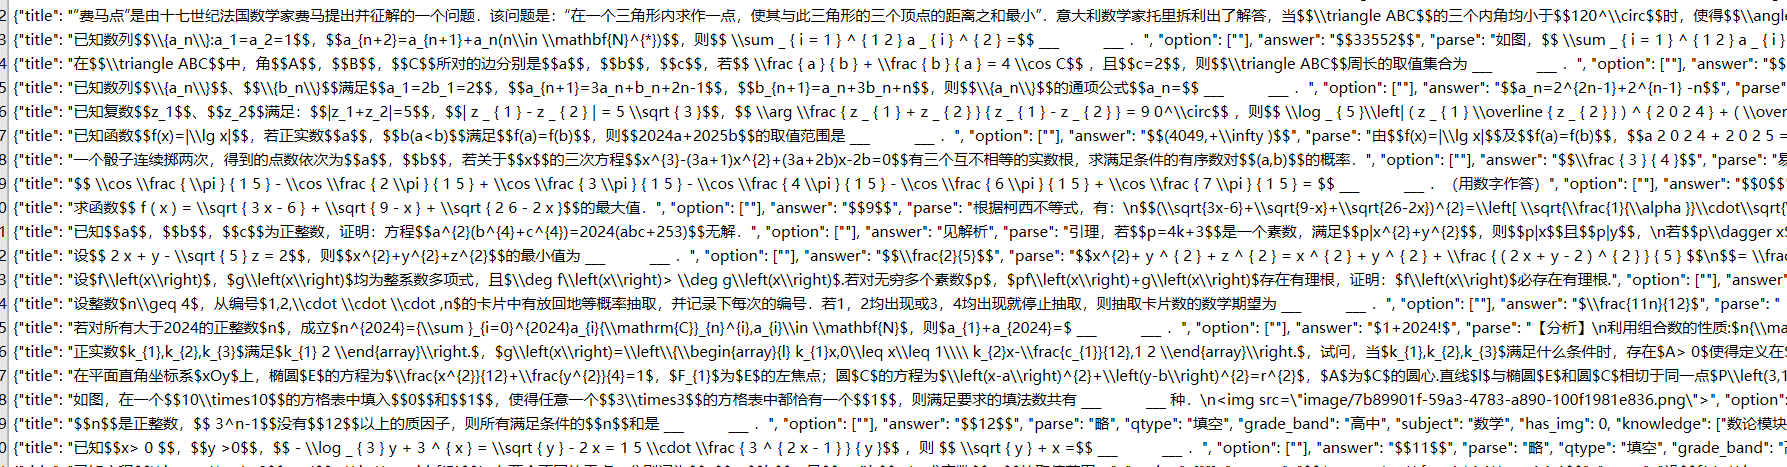
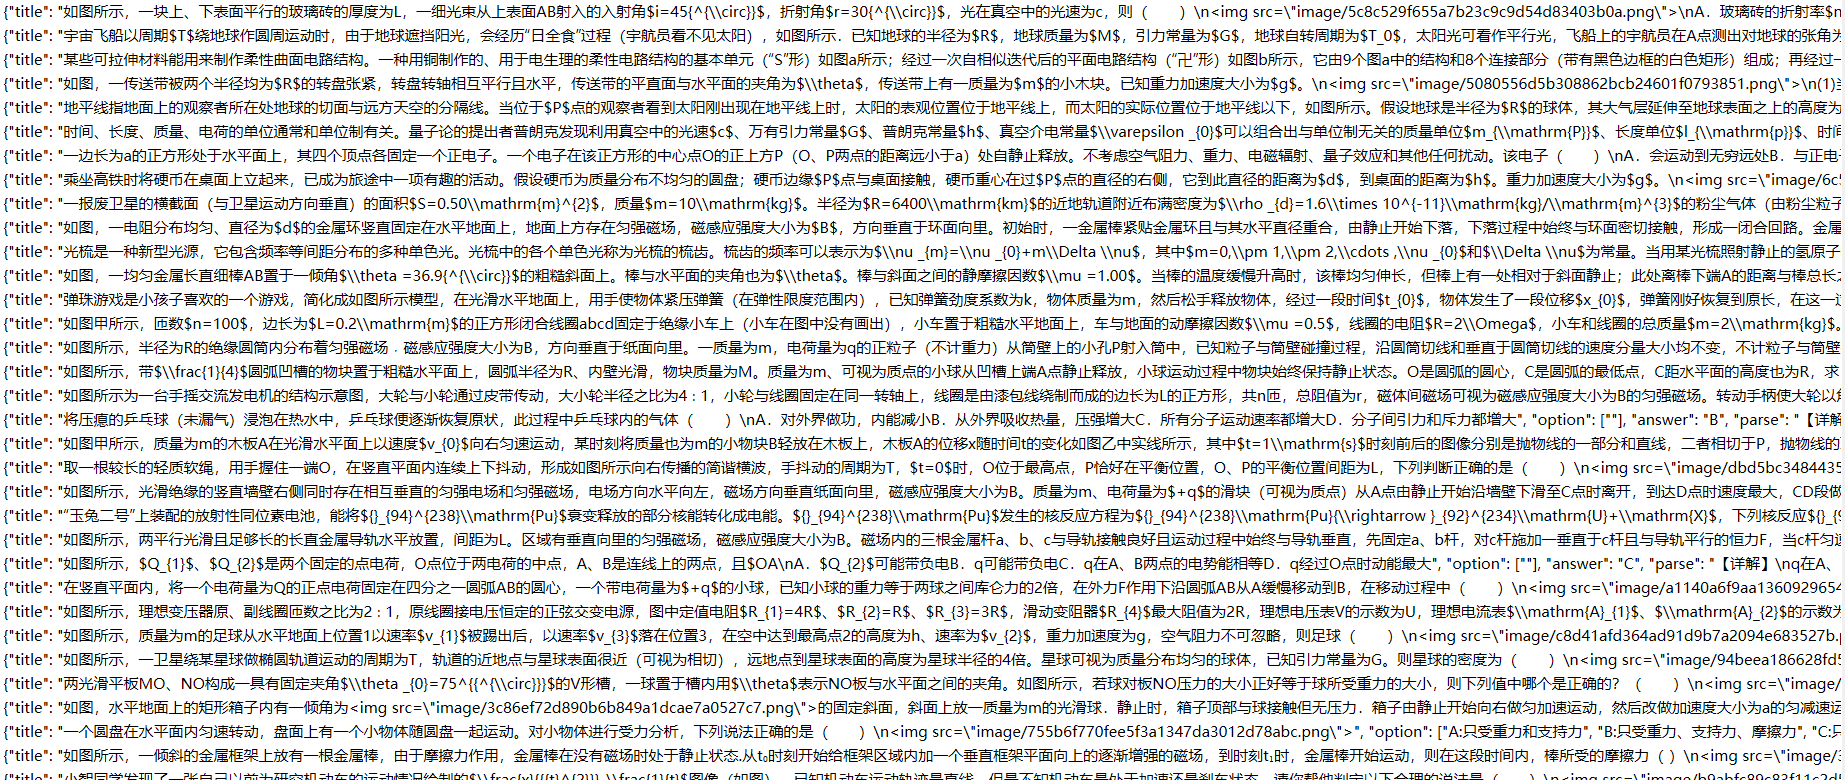
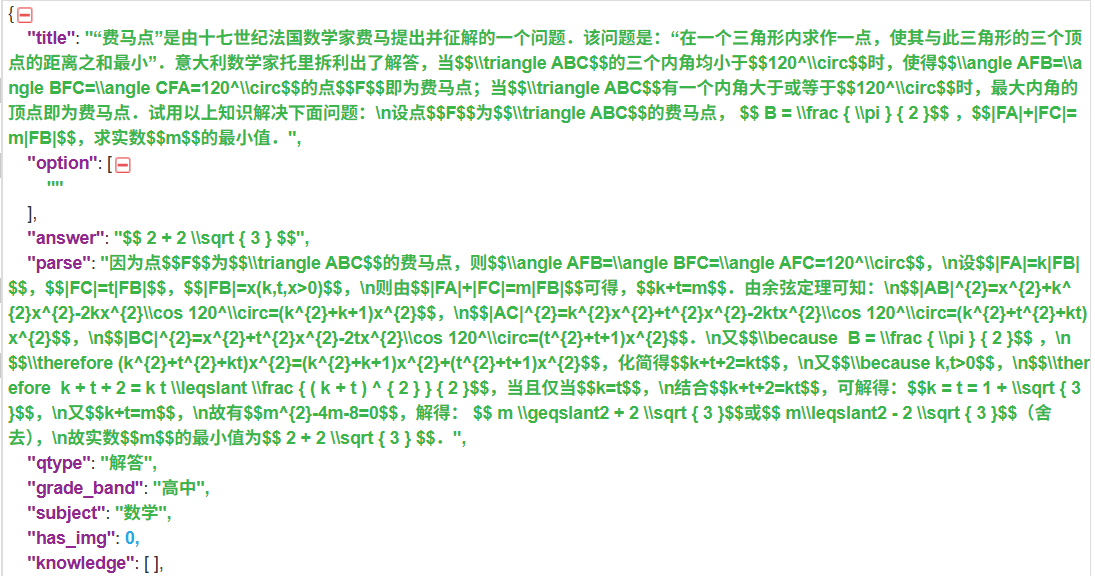
This dataset includes 114,000 structured Chinese academic contest questions from primary, middle, and high school levels. Subjects covered include mathematics, physics, chemistry, and biology. Each question is annotated with the question title, correct answer, parse (explanation), subject, grade level, and question type, making it highly suitable for fine-tuning educational large language models (LLMs) and intelligent tutoring systems. The data mirrors real-world Olympiad and competitive test formats in China, providing rich material for enhancing subject-specific knowledge and reasoning capabilities in AI systems. All data complies with global privacy regulations including GDPR, CCPA, and PIPL.
This is a paid datasets for commercial use, research purpose and more. Licensed ready made datasets help jump-start AI projects.
Specifications
Content
Contest questions text;
Data Size
About 114,000;
Data Fields
Contains title, answer, parse, subject, grade, question type, knowledge, has_img, There are some questions without parse;;
Subject categories
Primary, middle and high school science questions;
Format
Jsonl;
Language
Chinese;
Data processing
Subject, questions, parse and answers were analyzed, formula conversion and table format conversion were done, and content was also cleaned
Nexdata’s LLM datasets can support a wide range of large language model development tasks, including pre-training, supervised fine-tuning, instruction tuning, preference optimization, evaluation, and domain-specific model development. Depending on the dataset, data may include text, instruction-response pairs, conversations, question-answer pairs, reasoning data, and other structured or annotated content.
Can Nexdata customize LLM datasets based on our specific model and requirements?
Yes. If our off-the-shelf LLM datasets do not fully match your requirements, Nexdata provides flexible custom data collection, generation, annotation, curation, and quality control services. We can customize datasets based on your target languages, domains, use cases, data formats, task types, volume, and quality requirements to support specific LLM training and evaluation projects.
Can Nexdata provide large-scale and high-quality data for LLM development?
Yes. Nexdata can support large-scale LLM data projects across multiple languages, domains, and data types. Our data services include multi-stage quality control, data cleaning, annotation, validation, and curation to help ensure consistency and usability. For projects requiring data beyond our existing datasets, our customized data services can be scaled according to the required volume, specifications, and delivery schedule.


 Specifications
 Sample
 Recommended Dataset


