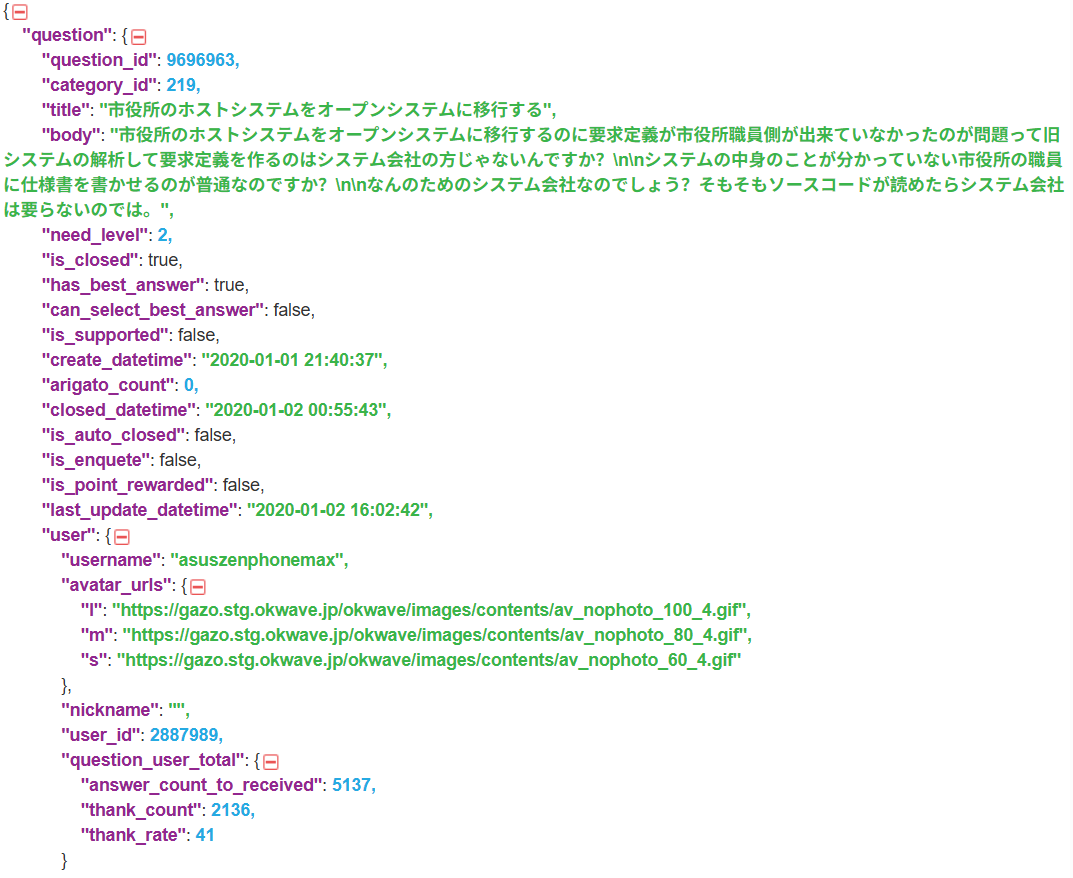
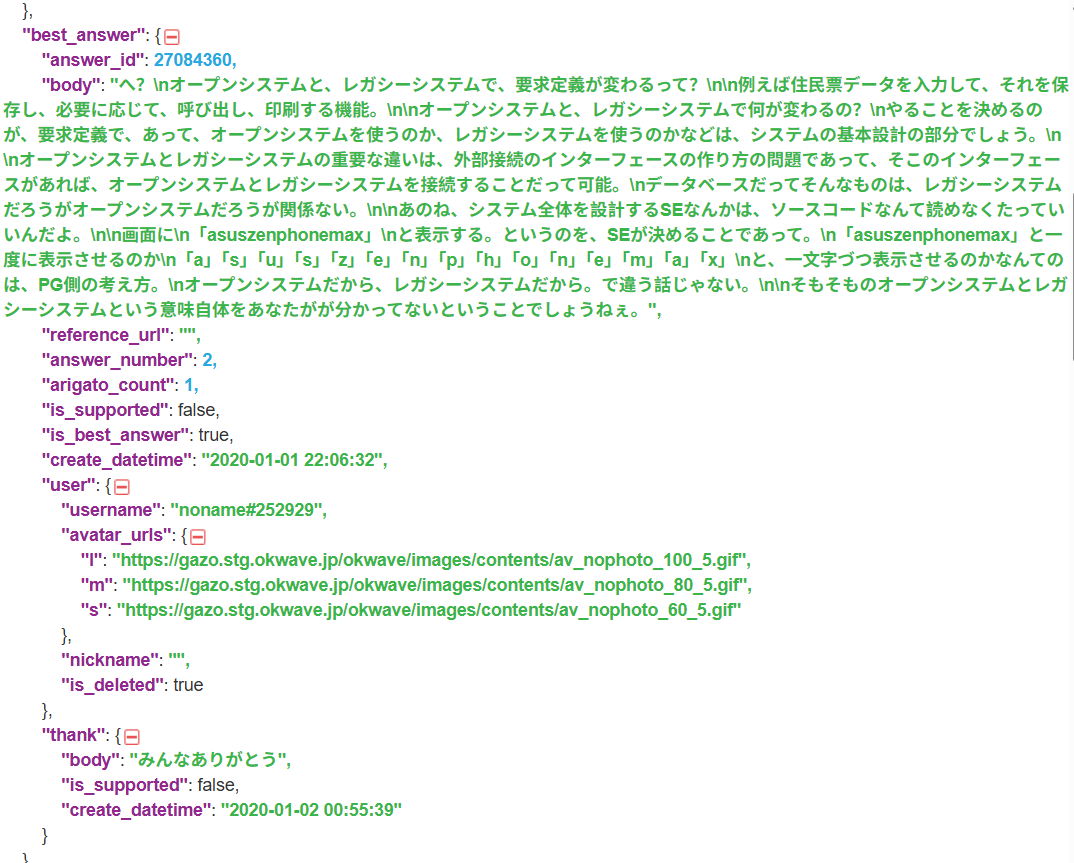
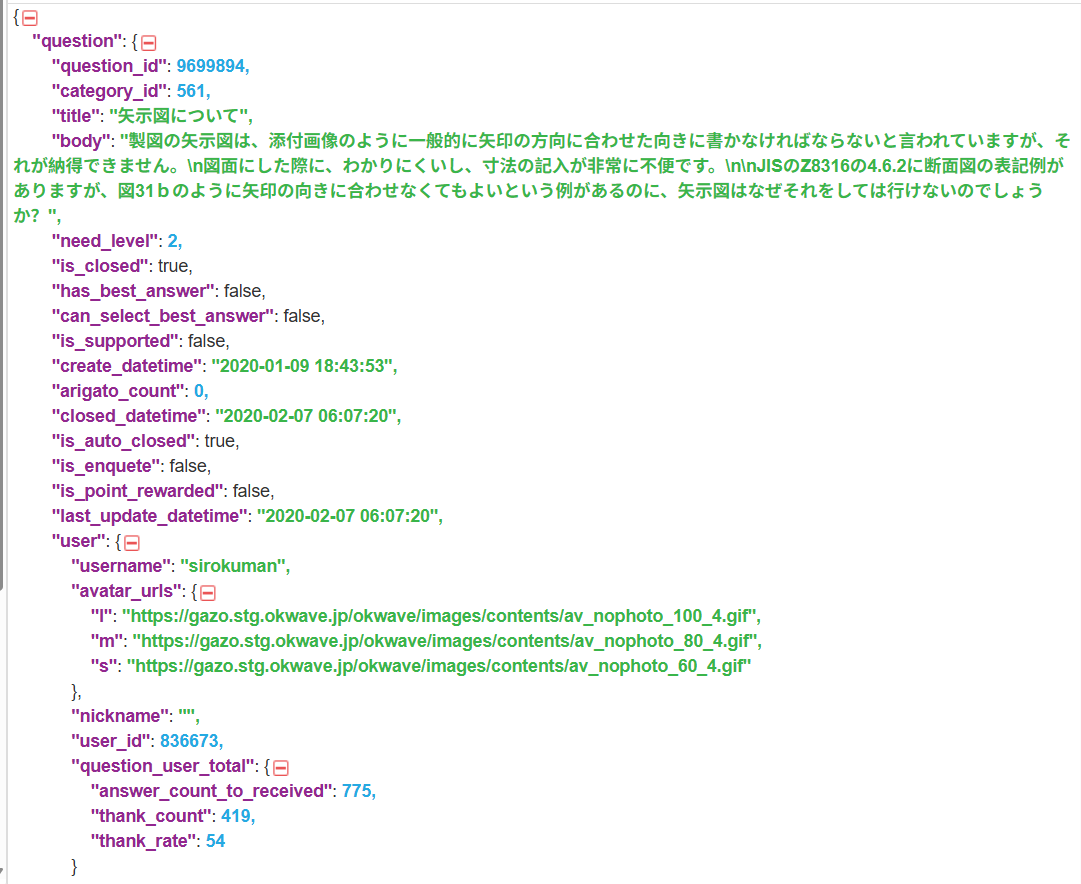
[{"@type":"PropertyValue","name":"Content","value":"OKWAVE Q&A text data, the platform authorization and copyright are clear;"},{"@type":"PropertyValue","name":"Data Size","value":"The data is continuously updated. As of the end of April 25, there were 8.4 million questions and 2.3 billion words. 27 million answers and 7.6 billion words; Thanks (the gratitude expressed by the questioner to the responder) 15.5 million pieces, 1.7 billion words; Supplementary explanations amount to 2.1 million pieces, totaling 360 million words;"},{"@type":"PropertyValue","name":"Data fields","value":"Contains question, answer, category, create_datetime, user, etc;"},{"@type":"PropertyValue","name":"Storage Format","value":"Json"},{"@type":"PropertyValue","name":"Language","value":"Japanese"}]
{"id":1840,"datatype":"1","titleimg":"https://www.nexdata.ai/shujutang/static/image/index/datatang_tuxiang_default.webp","type1":"226","type1str":null,"type2":"227","type2str":null,"dataname":"Japanese Q&A Dataset from OKWAVE – 8.4M Questions","datazy":[{"title":"Content","content":"OKWAVE Q&A text data, the platform authorization and copyright are clear;","desc":"Content"},{"title":"Data Size","content":"The data is continuously updated. As of the end of April 25, there were 8.4 million questions and 2.3 billion words. 27 million answers and 7.6 billion words; Thanks (the gratitude expressed by the questioner to the responder) 15.5 million pieces, 1.7 billion words; Supplementary explanations amount to 2.1 million pieces, totaling 360 million words;","desc":"Data Size"},{"title":"Data fields","content":"Contains question, answer, category, create_datetime, user, etc;","desc":"Data fields"},{"title":"Storage Format","content":"Json","desc":"Storage Format"},{"title":"Language","content":"Japanese","desc":"Language"}],"datatag":"Q&A,Text,Japanese","technologydoc":null,"downurl":null,"datainfo":null,"standard":null,"dataylurl":null,"flag":null,"publishtime":null,"createby":null,"createtime":null,"ext1":null,"samplestoreloc":null,"hosturl":null,"datasize":null,"industryPlan":null,"keyInformation":"","samplePresentation":[{"name":"1.png","url":"https://storage-product.datatang.com/damp/product/sample_presentation/20251013133323/1.png?Expires=4102415999&OSSAccessKeyId=LTAI5tEBeSWUJiqjXvBMsxEu&Signature=suJVU5qEJZI7cFfSmGbb%2FEH3O%2Fc%3D","intro":"","size":93090,"progress":100,"type":"jpg"},{"name":"2.png","url":"https://storage-product.datatang.com/damp/product/sample_presentation/20251013133323/2.png?Expires=4102415999&OSSAccessKeyId=LTAI5tEBeSWUJiqjXvBMsxEu&Signature=8VyLeLdVdYOPK5uOxWCTPVy%2B17k%3D","intro":"","size":138876,"progress":100,"type":"jpg"},{"name":"3.png","url":"https://storage-product.datatang.com/damp/product/sample_presentation/20251013133323/3.png?Expires=4102415999&OSSAccessKeyId=LTAI5tEBeSWUJiqjXvBMsxEu&Signature=TfchG2iN3SSpSSlkWCnK%2FwdA2Qw%3D","intro":"","size":87528,"progress":100,"type":"jpg"}],"officialSummary":"This dataset is collected from the Japanese OKWAVE Q&A platform and includes large-scale parsed and processed text data suitable for LLM training and Japanese natural language understanding. It contains structured fields such as questions, answers, categories, timestamps, user metadata, and supplementary explanations. As of April 2025, the dataset includes 8.4 million questions with 2.3 billion words, 27 million answers totaling 7.6 billion words, 15.5 million thank-you messages (1.7 billion words), and 2.1 million supplementary replies (360 million words). Continuously updated and rich in user-generated content, this dataset is ideal for building Japanese conversational AI, ChatGPT fine-tuning, question answering systems, text summarization, and semantic parsing models. All data complies with relevant data usage and privacy regulations.","dataexampl":null,"datakeyword":["Japanese Q&A dataset","OKWAVE forum data","Japanese language corpus","Japanese dialogue dataset","ChatGPT Japanese fine-tuning","user-generated content","question answer dataset"],"isDelete":null,"ids":null,"idsList":null,"datasetCode":null,"productStatus":null,"tagTypeEn":"Type","tagTypeZh":null,"website":null,"samplePresentationList":null,"datazyList":null,"keyInformationList":null,"dataexamplList":null,"bgimg":null,"datazyScriptList":null,"datakeywordListString":null,"sourceShowPage":"llm","dataShowType":"[{\"code\":\"1\",\"language\":\"ZH\"},{\"code\":\"2\",\"language\":\"EN,JP,PT,DE,KO,FR,ES\"},{\"code\":\"3\",\"language\":\"EN\"},{\"code\":\"4\",\"language\":\"JP\"}]","productNameEn":"Japanese OKWAVE Q&A platform Text Parsing and Processing Data","BGimg":"","voiceBg":["/shujutang/static/image/comm/audio_bg.webp","/shujutang/static/image/comm/audio_bg2.webp","/shujutang/static/image/comm/audio_bg3.webp","/shujutang/static/image/comm/audio_bg4.webp","/shujutang/static/image/comm/audio_bg5.webp"]}
https://www.nexdata.ai/shujutang/static/image/index/datatang_tuxiang_default.webp
[{"@type":"ImageObject","embedUrl":"https://storage-product.datatang.com/damp/product/sample_presentation/20251013133323/1.png?Expires=4102415999&OSSAccessKeyId=LTAI5tEBeSWUJiqjXvBMsxEu&Signature=suJVU5qEJZI7cFfSmGbb%2FEH3O%2Fc%3D"},{"@type":"ImageObject","embedUrl":"https://storage-product.datatang.com/damp/product/sample_presentation/20251013133323/2.png?Expires=4102415999&OSSAccessKeyId=LTAI5tEBeSWUJiqjXvBMsxEu&Signature=8VyLeLdVdYOPK5uOxWCTPVy%2B17k%3D"},{"@type":"ImageObject","embedUrl":"https://storage-product.datatang.com/damp/product/sample_presentation/20251013133323/3.png?Expires=4102415999&OSSAccessKeyId=LTAI5tEBeSWUJiqjXvBMsxEu&Signature=TfchG2iN3SSpSSlkWCnK%2FwdA2Qw%3D"}]
Japanese Q&A Dataset from OKWAVE – 8.4M Questions
Japanese Q&A dataset
OKWAVE forum data
Japanese language corpus
Japanese dialogue dataset
ChatGPT Japanese fine-tuning
user-generated content
question answer dataset
This dataset is collected from the Japanese OKWAVE Q&A platform and includes large-scale parsed and processed text data suitable for LLM training and Japanese natural language understanding. It contains structured fields such as questions, answers, categories, timestamps, user metadata, and supplementary explanations. As of April 2025, the dataset includes 8.4 million questions with 2.3 billion words, 27 million answers totaling 7.6 billion words, 15.5 million thank-you messages (1.7 billion words), and 2.1 million supplementary replies (360 million words). Continuously updated and rich in user-generated content, this dataset is ideal for building Japanese conversational AI, ChatGPT fine-tuning, question answering systems, text summarization, and semantic parsing models. All data complies with relevant data usage and privacy regulations.
This is a paid datasets for commercial use, research purpose and more. Licensed ready made datasets help jump-start AI projects.
![Specifications]()
Specifications
Content
OKWAVE Q&A text data, the platform authorization and copyright are clear;
Data Size
The data is continuously updated. As of the end of April 25, there were 8.4 million questions and 2.3 billion words. 27 million answers and 7.6 billion words; Thanks (the gratitude expressed by the questioner to the responder) 15.5 million pieces, 1.7 billion words; Supplementary explanations amount to 2.1 million pieces, totaling 360 million words;
Data fields
Contains question, answer, category, create_datetime, user, etc;
![Sample]()
Sample
Tell Us Your Special Needs

What can Nexdata’s LLM datasets be used for?

Nexdata’s LLM datasets can support a wide range of large language model development tasks, including pre-training, supervised fine-tuning, instruction tuning, preference optimization, evaluation, and domain-specific model development. Depending on the dataset, data may include text, instruction-response pairs, conversations, question-answer pairs, reasoning data, and other structured or annotated content.
Can Nexdata customize LLM datasets based on our specific model and requirements?
Yes. If our off-the-shelf LLM datasets do not fully match your requirements, Nexdata provides flexible custom data collection, generation, annotation, curation, and quality control services. We can customize datasets based on your target languages, domains, use cases, data formats, task types, volume, and quality requirements to support specific LLM training and evaluation projects.
Can Nexdata provide large-scale and high-quality data for LLM development?
Yes. Nexdata can support large-scale LLM data projects across multiple languages, domains, and data types. Our data services include multi-stage quality control, data cleaning, annotation, validation, and curation to help ensure consistency and usability. For projects requiring data beyond our existing datasets, our customized data services can be scaled according to the required volume, specifications, and delivery schedule.
26c02eea-3e81-4657-a6e7-ec29a61c2550


 Specifications
 Sample