[{"@type":"PropertyValue","name":"Data size","value":"9,574 images, 243,240 bounding boxes"},{"@type":"PropertyValue","name":"Language distribution","value":"English, Spanish, Portuguese, French, German, Japanese, Italian and Dutch"},{"@type":"PropertyValue","name":"Collecting environment","value":"black boards, white boards, green boards"},{"@type":"PropertyValue","name":"Device","value":"cellphone"},{"@type":"PropertyValue","name":"Photographic angle","value":"eye-level angle, looking down angle, looking up angle"},{"@type":"PropertyValue","name":"Data format","value":"the image data format is .jpg and other common image formats, the annotation file data format is.json"},{"@type":"PropertyValue","name":"Annotation content","value":"line-level quadrilateral (polygon) bounding box annotation and transcription for the texts"},{"@type":"PropertyValue","name":"Accuracy rate","value":"the error bound of each vertex of quadrilateral bounding box is within 5 pixels, which is a qualified annotation, the accuracy of bounding boxes is not less than 95%; the texts transcription accuracy is not less than 95%"}]
{"id":1522,"datatype":"1","titleimg":"https://www.nexdata.ai/shujutang/static/image/index/datatang_tuxiang_default.webp","type1":"147","type1str":null,"type2":"150","type2str":null,"dataname":"9,574 Images – Multilingual Handwriting OCR Dataset (8 Languages)","datazy":[{"title":"Data size","content":"9,574 images, 243,240 bounding boxes","desc":"Data size"},{"title":"Language distribution","content":"English, Spanish, Portuguese, French, German, Japanese, Italian and Dutch","desc":"Language distribution"},{"title":"Collecting environment","content":"black boards, white boards, green boards","desc":"Collecting environment"},{"title":"Device","content":"cellphone","desc":"Device"},{"title":"Photographic angle","content":"eye-level angle, looking down angle, looking up angle","desc":"Photographic angle"},{"title":"Data format","content":"the image data format is .jpg and other common image formats, the annotation file data format is.json","desc":"Data format"},{"title":"Annotation content","content":"line-level quadrilateral (polygon) bounding box annotation and transcription for the texts","desc":"Annotation content"},{"title":"Accuracy rate","content":"the error bound of each vertex of quadrilateral bounding box is within 5 pixels, which is a qualified annotation, the accuracy of bounding boxes is not less than 95%; the texts transcription accuracy is not less than 95%","desc":"Accuracy rate"}],"datatag":"Handwriting,OCR,Black board,White board,Green board","technologydoc":null,"downurl":null,"datainfo":null,"standard":null,"dataylurl":null,"flag":null,"publishtime":null,"createby":null,"createtime":null,"ext1":null,"samplestoreloc":null,"hosturl":null,"datasize":null,"industryPlan":null,"keyInformation":"","samplePresentation":[{"name":"English-1.jpg","url":"https://storage-product.datatang.com/damp/product/instructions_zh/20250520181645/English-1.jpg?Expires=4102415999&OSSAccessKeyId=LTAI5tEBeSWUJiqjXvBMsxEu&Signature=avTJb3O47GRlf350BDF64u7Pg1I%3D","intro":"","size":1563589,"progress":100,"type":"jpg"},{"name":"French.jpg","url":"https://storage-product.datatang.com/damp/product/instructions_zh/20250520181645/French.jpg?Expires=4102415999&OSSAccessKeyId=LTAI5tEBeSWUJiqjXvBMsxEu&Signature=I94DzxisImSVjIMOdYAr2oC5tqM%3D","intro":"","size":1028972,"progress":100,"type":"jpg"},{"name":"German.jpg","url":"https://storage-product.datatang.com/damp/product/instructions_zh/20250520181645/German.jpg?Expires=4102415999&OSSAccessKeyId=LTAI5tEBeSWUJiqjXvBMsxEu&Signature=vMIP6sYPAFSoLdpyUqVyw%2BQoUNA%3D","intro":"","size":3863985,"progress":100,"type":"jpg"}],"officialSummary":"This dataset includes 9,574 handwriting images across 8 languages, including English, Spanish Portuguese and more. The data diversity includes multiple collecting scenes, different text carriers and different photographic angles(looking up, eye-level, looking down). In terms of annotation, each text line is annotated with quadrilateral polygons and transcription. The dataset can be used for training and evaluating OCR models, handwriting recognition systems, and multilingual text extraction tasks in AI and computer vision.","dataexampl":null,"datakeyword":["handwriting OCR dataset","handwritten text recognition data","multi-language handwriting OCR data","OCR training data","polygon-annotated handwriting dataset"],"isDelete":null,"ids":null,"idsList":null,"datasetCode":null,"productStatus":null,"tagTypeEn":"Data Type,Language","tagTypeZh":null,"website":null,"samplePresentationList":null,"datazyList":null,"keyInformationList":null,"dataexamplList":null,"bgimg":null,"datazyScriptList":null,"datakeywordListString":null,"sourceShowPage":"ocr","dataShowType":"[{\"code\":\"0\",\"language\":\"ZH\"},{\"code\":\"1\",\"language\":\"ZH\"},{\"code\":\"2\",\"language\":\"EN,JP,PT,DE,KO,FR,ES\"},{\"code\":\"3\",\"language\":\"EN\"}]","productNameEn":"9,574 Images – Handwriting OCR Data On Board of 8 Languages","BGimg":"","voiceBg":["/shujutang/static/image/comm/audio_bg.webp","/shujutang/static/image/comm/audio_bg2.webp","/shujutang/static/image/comm/audio_bg3.webp","/shujutang/static/image/comm/audio_bg4.webp","/shujutang/static/image/comm/audio_bg5.webp"]}
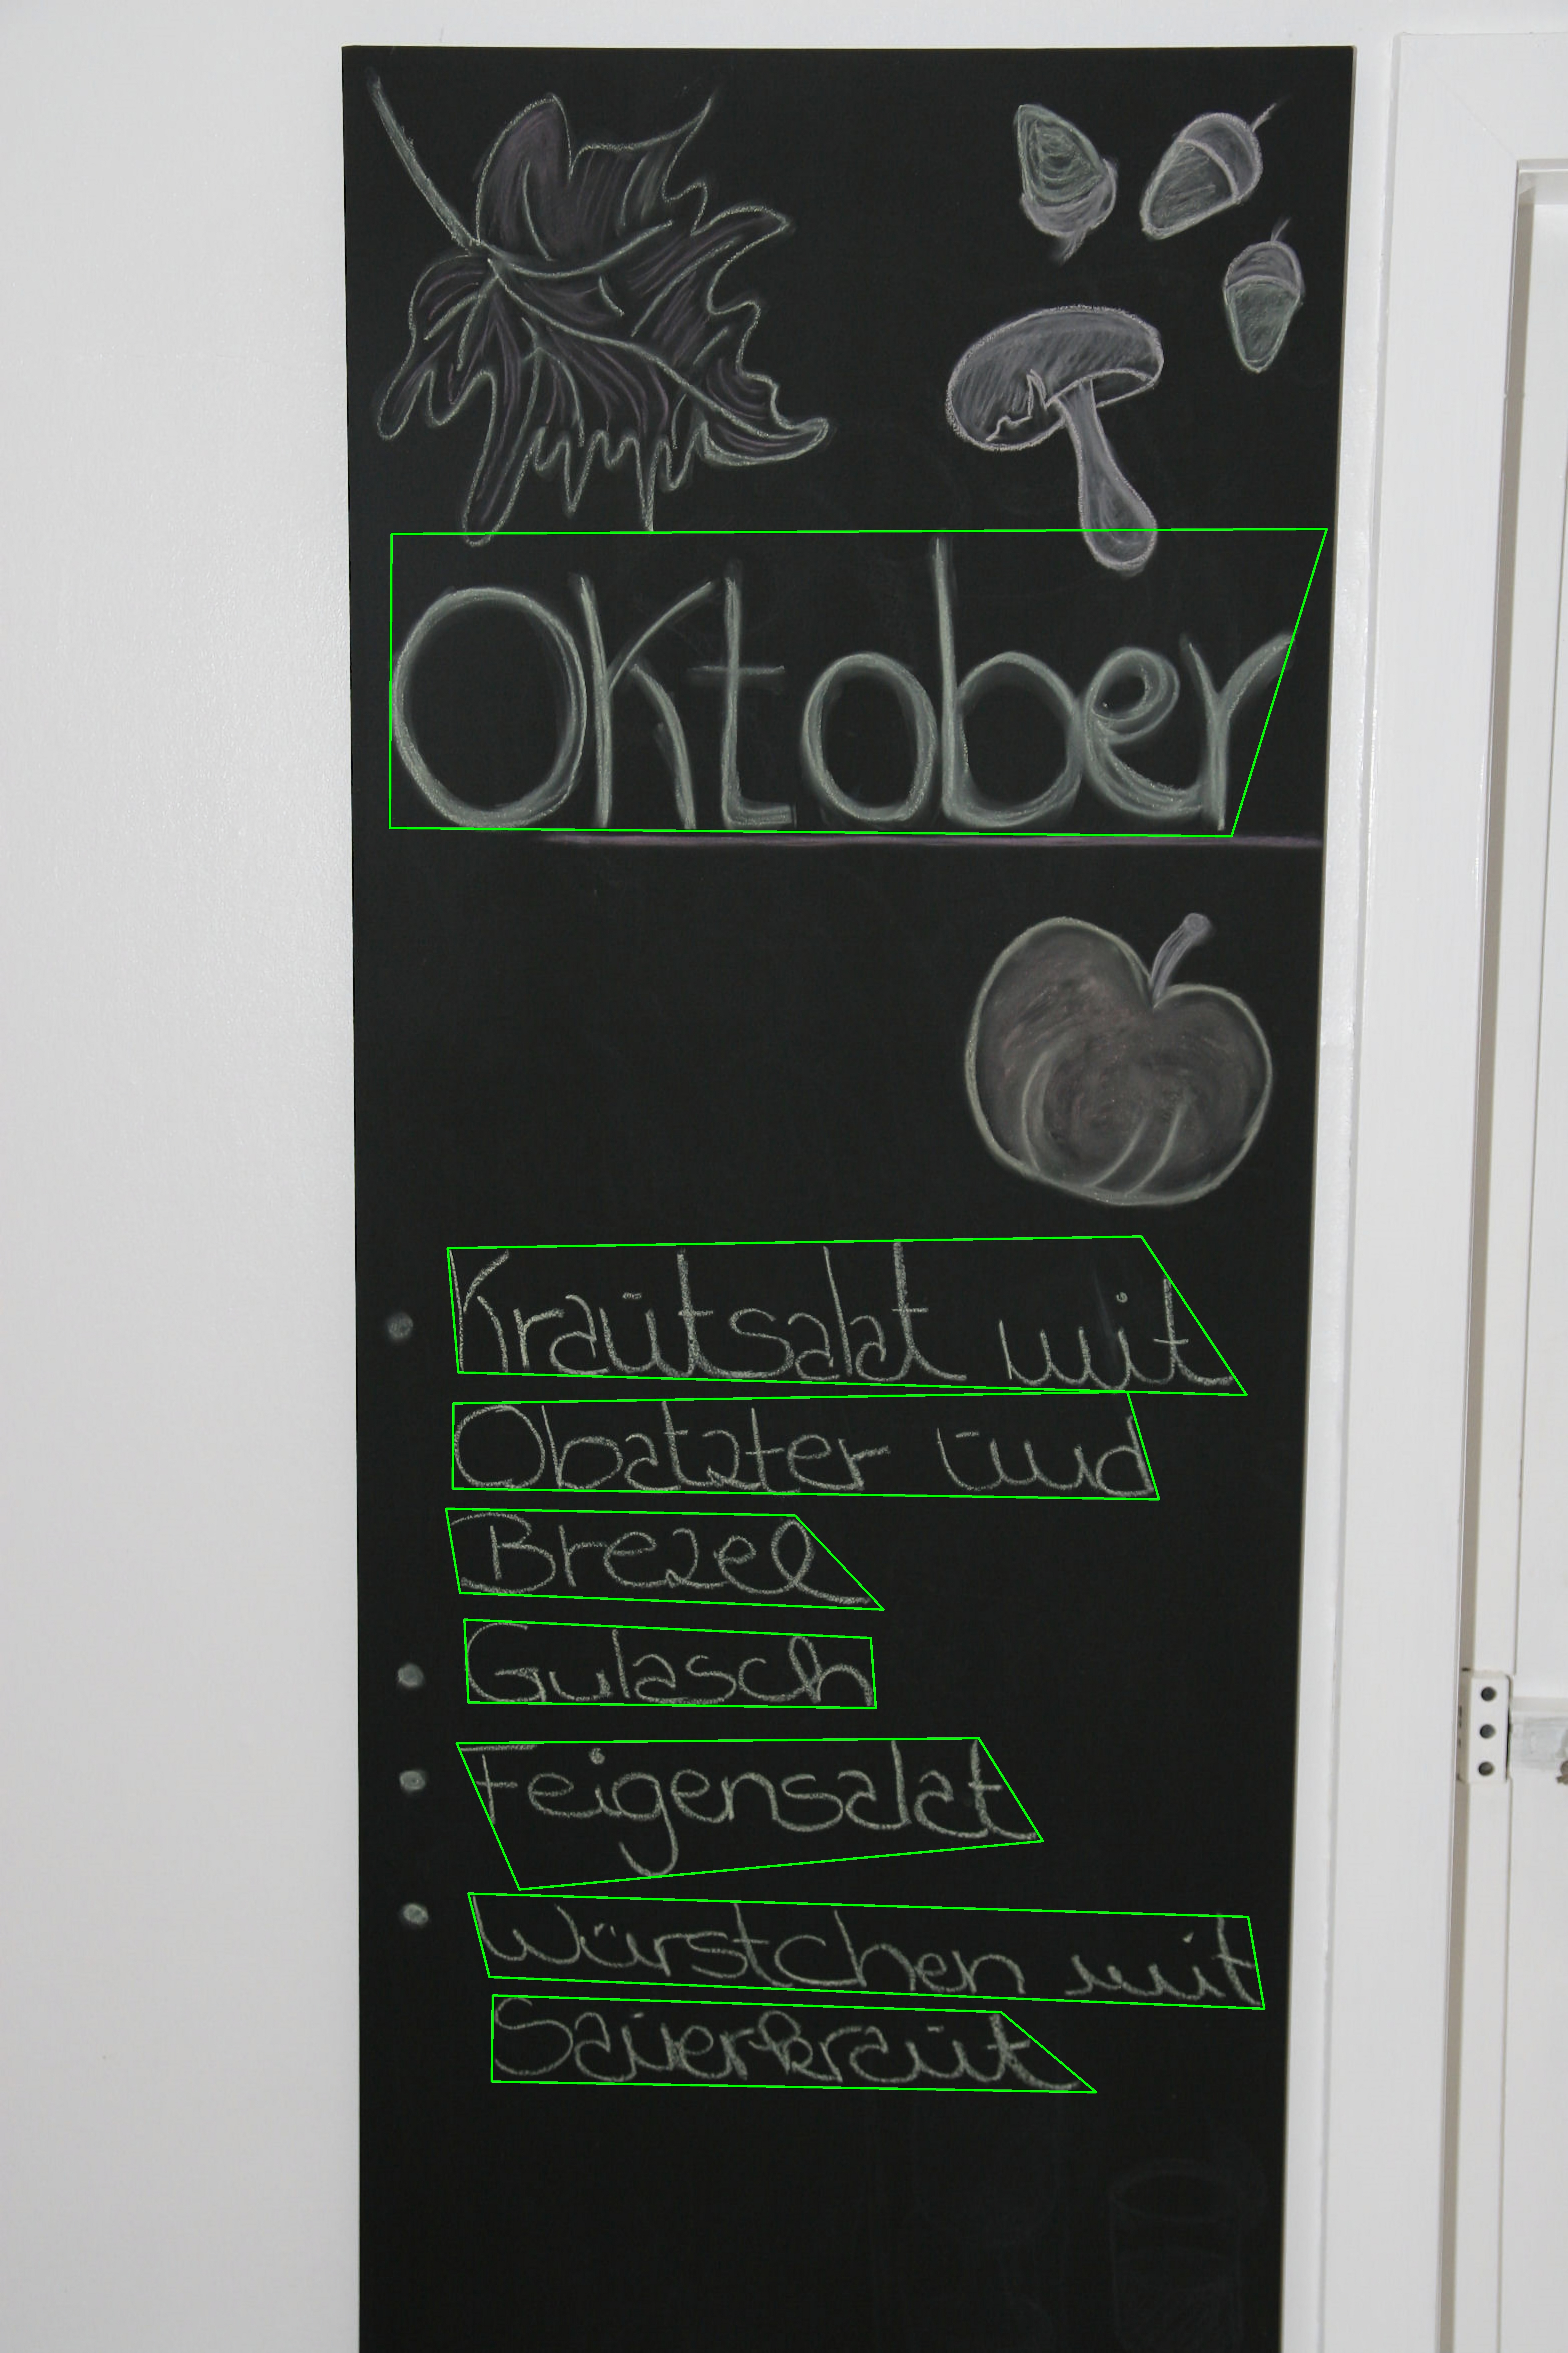
This dataset includes 9,574 handwriting images across 8 languages, including English, Spanish Portuguese and more. The data diversity includes multiple collecting scenes, different text carriers and different photographic angles(looking up, eye-level, looking down). In terms of annotation, each text line is annotated with quadrilateral polygons and transcription. The dataset can be used for training and evaluating OCR models, handwriting recognition systems, and multilingual text extraction tasks in AI and computer vision.
This is a paid datasets for commercial use, research purpose and more. Licensed ready made datasets help jump-start AI projects.
Specifications
Data size
9,574 images, 243,240 bounding boxes
Language distribution
English, Spanish, Portuguese, French, German, Japanese, Italian and Dutch
Collecting environment
black boards, white boards, green boards
Device
cellphone
Photographic angle
eye-level angle, looking down angle, looking up angle
Data format
the image data format is .jpg and other common image formats, the annotation file data format is.json
Annotation content
line-level quadrilateral (polygon) bounding box annotation and transcription for the texts
Accuracy rate
the error bound of each vertex of quadrilateral bounding box is within 5 pixels, which is a qualified annotation, the accuracy of bounding boxes is not less than 95%; the texts transcription accuracy is not less than 95%
Nexdata provides OCR datasets covering a wide range of data types, including documents, handwriting, invoices, test papers, and forms. The datasets cover diverse languages, layouts, text styles, and real-world scenarios to support OCR model training, text recognition, document analysis, and other document AI applications.
Can Nexdata customize OCR datasets for specific requirements?
Yes. If our off-the-shelf OCR datasets do not fully meet your requirements, Nexdata provides flexible custom data collection, annotation, and quality control services. We can customize datasets based on target languages, document types, handwriting styles, layouts, image conditions, data volume, and annotation specifications for specific OCR applications.
How does Nexdata ensure the quality and scalability of OCR datasets?
Nexdata applies multi-stage quality control throughout data collection, annotation, validation, and delivery. With extensive resources covering documents, handwriting, invoices, test papers, and forms, we can support both large-scale OCR projects and specialized datasets with customized formats, annotation requirements, and quality standards.


 Specifications
 Sample


 Recommended Dataset


