[{"@type":"PropertyValue","name":"Data content","value":"Text pairs of original and corrected texts for four European languages"},{"@type":"PropertyValue","name":"Data volume","value":"480000 pairs"},{"@type":"PropertyValue","name":"Languages","value":"French, German, Spanish, Italian"},{"@type":"PropertyValue","name":"Field","value":"input,output"},{"@type":"PropertyValue","name":"Format","value":"JSON"}]
{"id":1515,"datatype":"1","titleimg":"https://www.nexdata.ai/shujutang/static/image/index/datatang_tuxiang_default.webp","type1":"226","type1str":null,"type2":"228","type2str":null,"dataname":"Multilingual Grammar Correction Dataset – 480K Parallel Texts (DE, ES, FR, IT)","datazy":[{"title":"Data content","content":"Text pairs of original and corrected texts for four European languages","desc":"Data content"},{"title":"Data volume","content":"480000 pairs","desc":"Data volume"},{"title":"Languages","content":"French, German, Spanish, Italian","desc":"Languages"},{"title":"Field","content":"input,output","desc":"Field"},{"title":"Format","content":"JSON","desc":"Format"}],"datatag":"German, French, Spanish, Italian, proofreading","technologydoc":null,"downurl":null,"datainfo":null,"standard":null,"dataylurl":null,"flag":null,"publishtime":null,"createby":null,"createtime":null,"ext1":null,"samplestoreloc":null,"hosturl":null,"datasize":null,"industryPlan":null,"keyInformation":"","samplePresentation":[{"name":"德语样例.png","url":"https://storage-product.datatang.com/damp/product/sample_presentation/20250718142728/%E5%BE%B7%E8%AF%AD%E6%A0%B7%E4%BE%8B.png?Expires=4102415999&OSSAccessKeyId=LTAI5tEBeSWUJiqjXvBMsxEu&Signature=Mbhy3eB1XV18Pz7ETquxq%2FQXDYI%3D","intro":"","size":14337,"progress":100,"type":"jpg"},{"name":"法语样例.png","url":"https://storage-product.datatang.com/damp/product/sample_presentation/20250718142728/%E6%B3%95%E8%AF%AD%E6%A0%B7%E4%BE%8B.png?Expires=4102415999&OSSAccessKeyId=LTAI5tEBeSWUJiqjXvBMsxEu&Signature=M9EUDtOgF6kOmlk7TT21dtmjIWk%3D","intro":"","size":7576,"progress":100,"type":"jpg"},{"name":"西班牙语样例.png","url":"https://storage-product.datatang.com/damp/product/sample_presentation/20250718142728/%E8%A5%BF%E7%8F%AD%E7%89%99%E8%AF%AD%E6%A0%B7%E4%BE%8B.png?Expires=4102415999&OSSAccessKeyId=LTAI5tEBeSWUJiqjXvBMsxEu&Signature=sumS6I20jDUhBN5xTw5ESzU6aSo%3D","intro":"","size":10686,"progress":100,"type":"jpg"}],"officialSummary":"This dataset focuses on the four major European languages (French, German, Spanish, Italian) and contains 480000 pairs of original and corrected text pairs. Each piece of data is presented in JSON format, including two fields: input (raw text) and output (corrected text), which can assist in natural language processing, machine translation, and language teaching research.","dataexampl":null,"datakeyword":["Multilingual Grammar Correction Dataset","Grammar Correction Dataset"],"isDelete":null,"ids":null,"idsList":null,"datasetCode":null,"productStatus":null,"tagTypeEn":"Type","tagTypeZh":null,"website":null,"samplePresentationList":null,"datazyList":null,"keyInformationList":null,"dataexamplList":null,"bgimg":null,"datazyScriptList":null,"datakeywordListString":null,"sourceShowPage":"llm","dataShowType":"[{\"code\":\"0\",\"language\":\"ZH\"},{\"code\":\"1\",\"language\":\"ZH\"},{\"code\":\"2\",\"language\":\"EN,PT,DE,KO,FR,ES\"},{\"code\":\"3\",\"language\":\"EN\"},{\"code\":\"4\",\"language\":\"JP\"}]","productNameEn":"480000 corrected texts in German, Spanish, French, Italian","BGimg":"","voiceBg":["/shujutang/static/image/comm/audio_bg.webp","/shujutang/static/image/comm/audio_bg2.webp","/shujutang/static/image/comm/audio_bg3.webp","/shujutang/static/image/comm/audio_bg4.webp","/shujutang/static/image/comm/audio_bg5.webp"],"firstList":[{"name":"意大利语样例.png","url":"https://storage-product.datatang.com/damp/product/sample_presentation/20250718142728/%E6%84%8F%E5%A4%A7%E5%88%A9%E8%AF%AD%E6%A0%B7%E4%BE%8B.png?Expires=4102415999&OSSAccessKeyId=LTAI5tEBeSWUJiqjXvBMsxEu&Signature=vKA%2BnWeV2e3sUC2bKtfNCE2JnQc%3D","intro":"","size":8202,"progress":100,"type":"jpg"}]}
https://www.nexdata.ai/shujutang/static/image/index/datatang_tuxiang_default.webp
[{"@type":"ImageObject","embedUrl":"https://storage-product.datatang.com/damp/product/sample_presentation/20250718142728/%E5%BE%B7%E8%AF%AD%E6%A0%B7%E4%BE%8B.png?Expires=4102415999&OSSAccessKeyId=LTAI5tEBeSWUJiqjXvBMsxEu&Signature=Mbhy3eB1XV18Pz7ETquxq%2FQXDYI%3D"},{"@type":"ImageObject","embedUrl":"https://storage-product.datatang.com/damp/product/sample_presentation/20250718142728/%E6%B3%95%E8%AF%AD%E6%A0%B7%E4%BE%8B.png?Expires=4102415999&OSSAccessKeyId=LTAI5tEBeSWUJiqjXvBMsxEu&Signature=M9EUDtOgF6kOmlk7TT21dtmjIWk%3D"},{"@type":"ImageObject","embedUrl":"https://storage-product.datatang.com/damp/product/sample_presentation/20250718142728/%E8%A5%BF%E7%8F%AD%E7%89%99%E8%AF%AD%E6%A0%B7%E4%BE%8B.png?Expires=4102415999&OSSAccessKeyId=LTAI5tEBeSWUJiqjXvBMsxEu&Signature=sumS6I20jDUhBN5xTw5ESzU6aSo%3D"},{"@type":"ImageObject","embedUrl":"https://storage-product.datatang.com/damp/product/sample_presentation/20250718142728/%E6%84%8F%E5%A4%A7%E5%88%A9%E8%AF%AD%E6%A0%B7%E4%BE%8B.png?Expires=4102415999&OSSAccessKeyId=LTAI5tEBeSWUJiqjXvBMsxEu&Signature=vKA%2BnWeV2e3sUC2bKtfNCE2JnQc%3D"}]
Multilingual Grammar Correction Dataset – 480K Parallel Texts (DE, ES, FR, IT)
Multilingual Grammar Correction Dataset
Grammar Correction Dataset
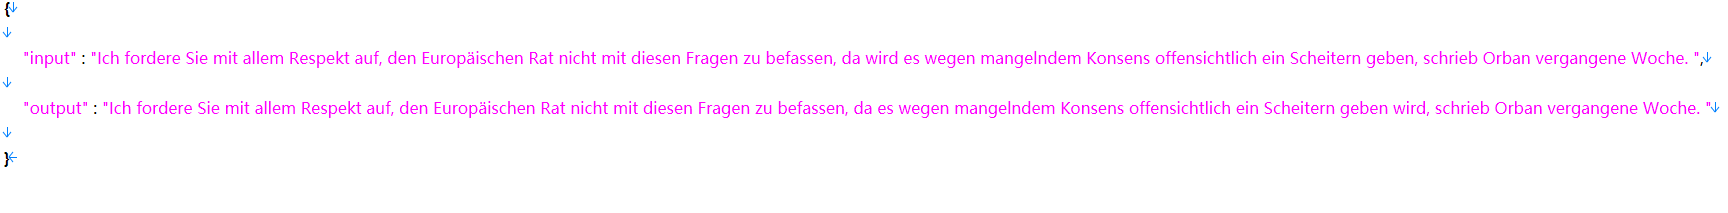
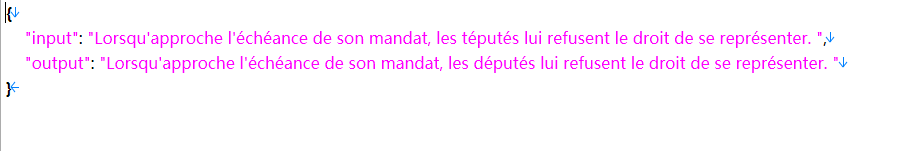
This dataset focuses on the four major European languages (French, German, Spanish, Italian) and contains 480000 pairs of original and corrected text pairs. Each piece of data is presented in JSON format, including two fields: input (raw text) and output (corrected text), which can assist in natural language processing, machine translation, and language teaching research.
This is a paid dataset licensed for commercial use. Ready-made datasets are available for immediate integration into AI projects.
![Specifications]()
Specifications
Data content
Text pairs of original and corrected texts for four European languages
Languages
French, German, Spanish, Italian
![Sample]()
Sample
![Recommended Datasets]()
Recommended Dataset
Tell Us Your Special Needs
Dataset FAQs

What can Nexdata’s LLM datasets be used for?

Nexdata’s LLM datasets can support a wide range of large language model development tasks, including pre-training, supervised fine-tuning, instruction tuning, preference optimization, evaluation, and domain-specific model development. Depending on the dataset, data may include text, instruction-response pairs, conversations, question-answer pairs, reasoning data, and other structured or annotated content.
Can Nexdata customize LLM datasets based on our specific model and requirements?
Yes. If our off-the-shelf LLM datasets do not fully match your requirements, Nexdata provides flexible custom data collection, generation, annotation, curation, and quality control services. We can customize datasets based on your target languages, domains, use cases, data formats, task types, volume, and quality requirements to support specific LLM training and evaluation projects.
Can Nexdata provide large-scale and high-quality data for LLM development?
Yes. Nexdata can support large-scale LLM data projects across multiple languages, domains, and data types. Our data services include multi-stage quality control, data cleaning, annotation, validation, and curation to help ensure consistency and usability. For projects requiring data beyond our existing datasets, our customized data services can be scaled according to the required volume, specifications, and delivery schedule.
1f168340-e06a-4bc3-b7b7-c3119d1a7f67


 Specifications
 Sample



 Recommended Dataset


